The file arrives as a JPEG. A phone screenshot of a bank statement, cropped to the page, slightly tilted. No producer string. No fonts. No revision history. No content stream. Just a flat rectangle of pixels.
A few months ago we wrote a long piece about what a PDF can't hide: the editor markers, the font tables, the incremental saves that keep a file's own edit history. All true. All gone here. This file has nothing left to hide, because whoever made it threw the file structure away.
When the file stops talking, the document still has to.
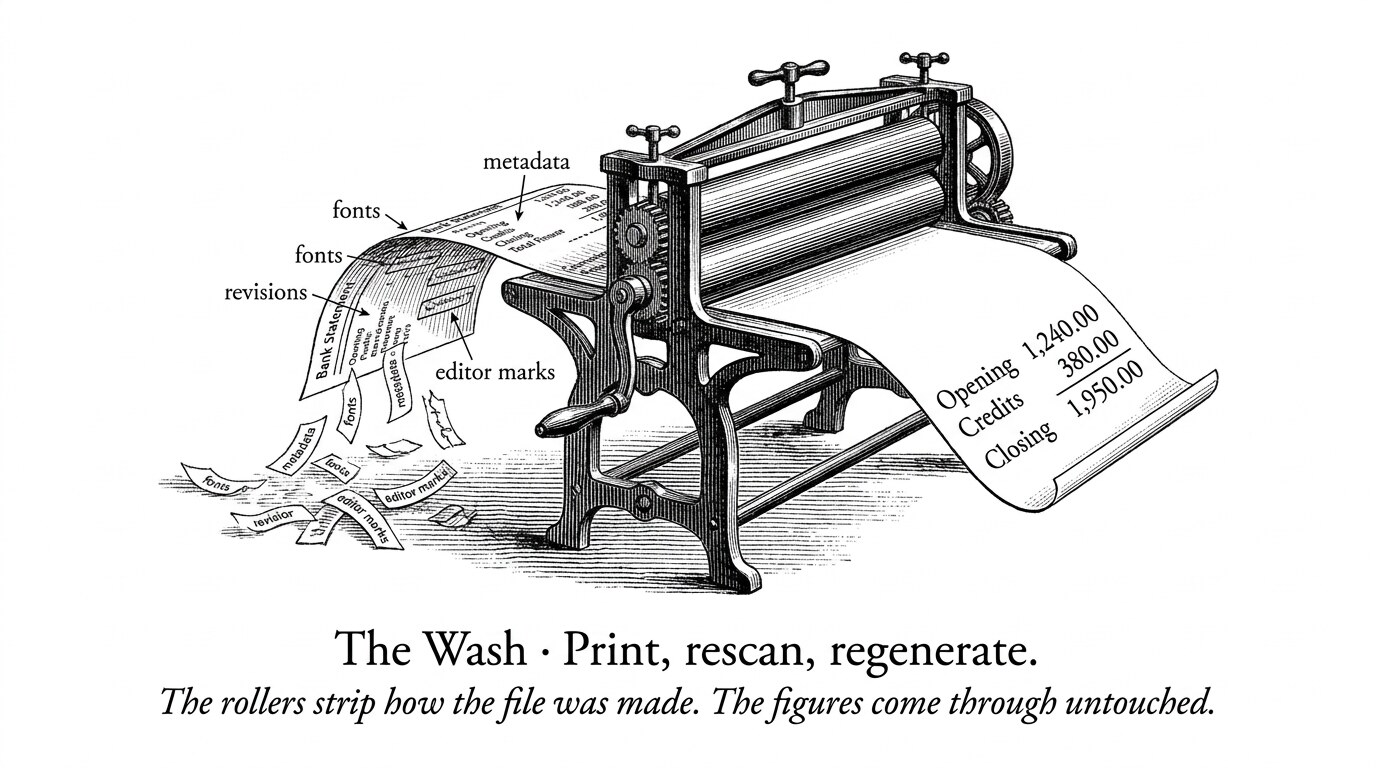
Three ways to wash a document
Structural forensics has a blind spot every serious forger has found: it inspects the file's container, and the container is optional.
There are three common ways to throw it away.
- Print and rescan. The edit happens in a PDF editor, the result goes through a printer and a scanner, and what comes out is an honest scan of a dishonest page. Every structural trace stays on the first computer.
- Regenerate. Hand the page to an image model with "change the closing balance to 4,820.00". It returns a new image. Not an edited file: a new one, with no history at all.
- Hop formats. Export to PDF, screenshot it, send the screenshot, let the receiving system wrap it back into a PDF. Each conversion launders a little more.
What comes out in the wash
The same forged statement, delivered four ways. The evidence about how the file was made disappears. What the document claims comes through untouched.
| Evidence | Edited PDF | Print & rescan | AI regenerated | Screenshot hop |
|---|---|---|---|---|
| How the file was made | ||||
| Editor markers in the page | present | gone | gone | gone |
| Fonts, revisions, object history | present | gone | gone | gone |
| Producer and metadata | present | scanner's | gone | converter's |
| What the document claims | ||||
| Balances, totals, running sums | intact | intact | intact | intact |
| IBAN and RIB check digits | intact | intact | intact | intact |
| Issuer-signed 2D-Doc seal | intact | intact | redrawn | intact |
| The issuer's visual identity | intact | intact | intact | intact |
A detector that only reads the file is stuck with two bad options when a scan arrives. To the file, every scan looks the same: a new producer, no fonts, one image per page, edited or not. So it either treats every scan as suspect, and analysts learn to ignore it, or waves every scan through, and forgers learn to print.
Either way, it's judging the scanner, not the edit.
What survives the wash
Here is the thing a forger can't launder: the claims.
A bank statement claims an opening balance, a list of transactions, a closing balance, and a statement period. It claims an IBAN whose check digits are computed from the rest of it. It claims to come from a specific bank, with that bank's header and layout. A French tax notice may carry a seal that the issuing administration signed with its private key.
Printing doesn't erase any of that. Passing the page through an image model doesn't erase it either: it just makes consistency the forger's problem. So the question flips. Not "how was this file made?" but "can this document be true?"
That shift forced us to change how we weigh evidence. Today, every one of our 92 signals belongs to one of four tiers, and the tier decides what a signal is allowed to do to a verdict.
Not all evidence is allowed to condemn
A signal's tier, not its count, decides what it can do to a verdict. Twenty odd counts still add up to "worth a look".
Structural forensics lives mostly in the middle two tiers. Washing destroys both. Contradictions are the evidence that survives the wash, so that's where we dug.
Arithmetic, to the cent
A balance equation is the oldest check in the book: opening balance, plus credits, minus debits, equals closing balance. Everyone says they do it. The details decide whether it works or lies to you.
The tolerance. Our extraction pipeline reconciles balances with a €0.02 tolerance, because a model reading a noisy scan will occasionally drop a cent and we don't want to fail an honest statement over it. The fraud check uses €0.005. Two one-cent edits move a balance by exactly €0.02, and a forger who knows your tolerance knows how much they can steal per row.
More than one equation. A statement prints the same truth several times. The totals row has to equal the sum of the rows. The header summary has to equal the totals. An intermediate balance printed mid-table (a month-end "SOLDE AU 30/11" line) has to match the running total at that exact line. Change one transaction, and a forger now has four numbers to repair instead of one.
The forger fixed the closing balance. Three other equations still disagree.
A salary credit raised by €1,000, and the closing balance raised to match, so the classic balance check passes. The statement prints the same truth in three more places, and nobody fixed those.
| Date · label | Debit | Credit | Balance |
|---|---|---|---|
| 01/10 · Opening balance | 2,104.30 | ||
| 02/10 · Salary, ACME SAS | 2,480.00edited | ||
| 05/10 · Rent | 850.00 | ||
| Balance at 15/10 | 2,734.30 | ||
| 18/10 · Card payments | 127.45 | ||
| 24/10 · Incoming transfer | 300.00 | ||
| Totals | 977.45 | 1,780.00 | |
| 31/10 · Closing balance | 3,906.85edited too |
Dates and identifiers. Every transaction should sit inside the printed period. A period shouldn't end before it starts. An IBAN carries a MOD-97 checksum, and a French one also carries a RIB key. Change one digit and both break, unless the forger recomputes them.
Here is what happened when we forged born-digital statements in place (same font, clean save, no structural trace at all) and ran them with these checks off, then on:
Edits the file can't see, caught by the page
Each of these edits leaves the PDF structurally clean. Before the content checks, all four were caught 0 times.
Zero before, because these edits were saved cleanly, in place, in the same font. The file had nothing to say about them. The page did.
The scars
Two things we learned the hard way.
Never trust a year you inferred. Many statements print "31.10" with no year, and every parser guesses it. On one bank's genuine statements, our parser put value dates exactly one year early whenever a transaction crossed a month boundary: 364 days off, on every sample. A date check that trusted that guess would have flagged every honest customer of that bank. A date only counts as evidence when the bank printed its year.
A coherence check is a claim about your reader as much as about the document. When we first ran the balance check across raw production statements, it fired on 19% of them. That wasn't a fraud wave. It was our parser misreading rows, typically finding a row without its amount. An arithmetic contradiction is only evidence if you are certain you read the numbers right. So the check runs only where we read the PDF's own text directly, on born-digital pages, with no OCR in between. And on its own it raises a warning, not a verdict.
You don't need a forger to fail a balance check. You just need a parser bug.
The text that says one thing and draws another
There's a catch in "read the PDF's own text directly". A forger who knows we trust born-digital text can skip the wash entirely and lie to the parser instead. Every extraction pipeline reads the text layer, ours and every LLM pipeline included, which makes the text layer itself an attack surface.
A PDF can attach a /ActualText replacement to a run of glyphs, drawing one figure on screen while feeding another to every text extractor. A font's /ToUnicode map can be rewired so the shape is a 7 and the copied text is a 1. The human underwriter sees one statement. The automated balance check validates another. Both pass, because they are reading two different documents.
One page, two documents
The glyphs and the text layer are separate things in a PDF. Nothing forces them to agree.
BT /F1 11 Tf 412 318 Td
/Span << /ActualText (1,450.00) >> BDC
  (9,450.00) Tj            % the glyphs a human sees
EMC
ETSo we stopped trusting the text layer for numbers. We take each digit a font claims to draw, render it alone, read it back with OCR, and compare that with the text layer. In our benchmark this caught 101 of 101 /ActualText swaps, with zero firings across 208 genuine files.
We met a cruder version of the same idea in production, on a statement claiming to come from a major French bank. The forger didn't bother deleting the original transactions: they drew opaque white rectangles over the rows and typed new figures on top, 48,00 sitting directly over 162,00. At the time, our engine scored it normal. Today we check the drawing order for amounts buried under a later opaque fill with new text drawn over them, and it scores high risk. (The check needs both halves. A white fill alone fired on 13 genuine files, because some print drivers shade table cells after drawing the text.)
If your fraud check and your extractor read the same text layer, a forger only has to fool it once.
Cryptography survives the scanner
Every check so far asks whether the document agrees with itself. A careful forger can win that game. If they change a transaction and then carefully update the totals row, the header summary and the running balance, arithmetic alone won't catch them.
Some documents carry a check that no amount of care defeats. French administrations and utilities print a 2D-Doc: a Data Matrix barcode holding the document's key fields (name, address, tax amounts, reference period), signed with the issuer's private key under the ANTS standard.
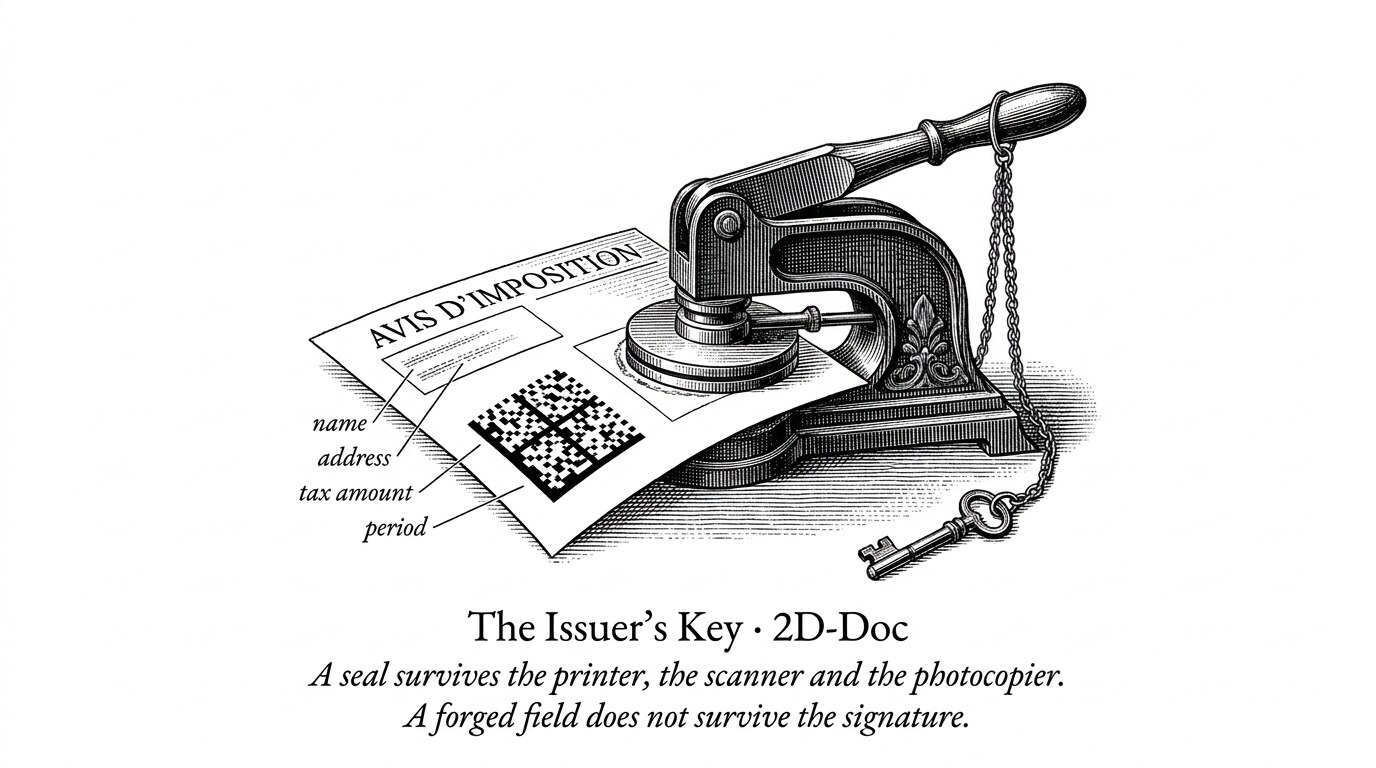
The seal has a property structural evidence never had: it survives the wash. A barcode prints and rescans perfectly well.
Checking a document against its issuer, not against itself
The seal is read from the pixels, so it works on a scan, a photo or a print of a print.
That last case came from a cluster of tax notices built with a desktop-publishing kit. The barcode looked right. Someone drew a picture of a seal, hoping nobody would scan it.
The strongest coherence check isn't the document agreeing with itself. It's the document agreeing with its issuer's key.
Does it look like who it claims to be?
The cheapest forgery doesn't touch the numbers. It takes a genuine statement from a small bank and pastes a big bank's header on top.
The numbers are honest. Only the letterhead lies. So we compare the page, patch by patch, against verified reference pages for each bank family and ask which one it actually resembles. When the bank it names and the bank it looks like disagree by a clear margin, we flag the mismatch.
On a held-out test set, this caught 75% of header-swap fakes while firing on just 1 of 213 genuine documents. That one false positive is instructive: a file whose first page was the bank's back page, which looks like nobody's header.
And yes, the pixels
None of this means we ignore the image. When a document is regenerated by an image model, the pixels are the only place the model leaves a signature.
Generic AI-image detectors are trained on photos, and documents aren't photos. We tested one on AI-regenerated document pages, at a threshold that flags only 1% of genuine documents (measured on about 825 genuine pages per channel, because a noisy detector is one analysts learn to switch off). It caught 20%. Fine-tuned on document pages, the same architecture caught 90% after our upload conversion, 85% after a trip through WhatsApp, and 95% on pages from an image model it never saw in training.
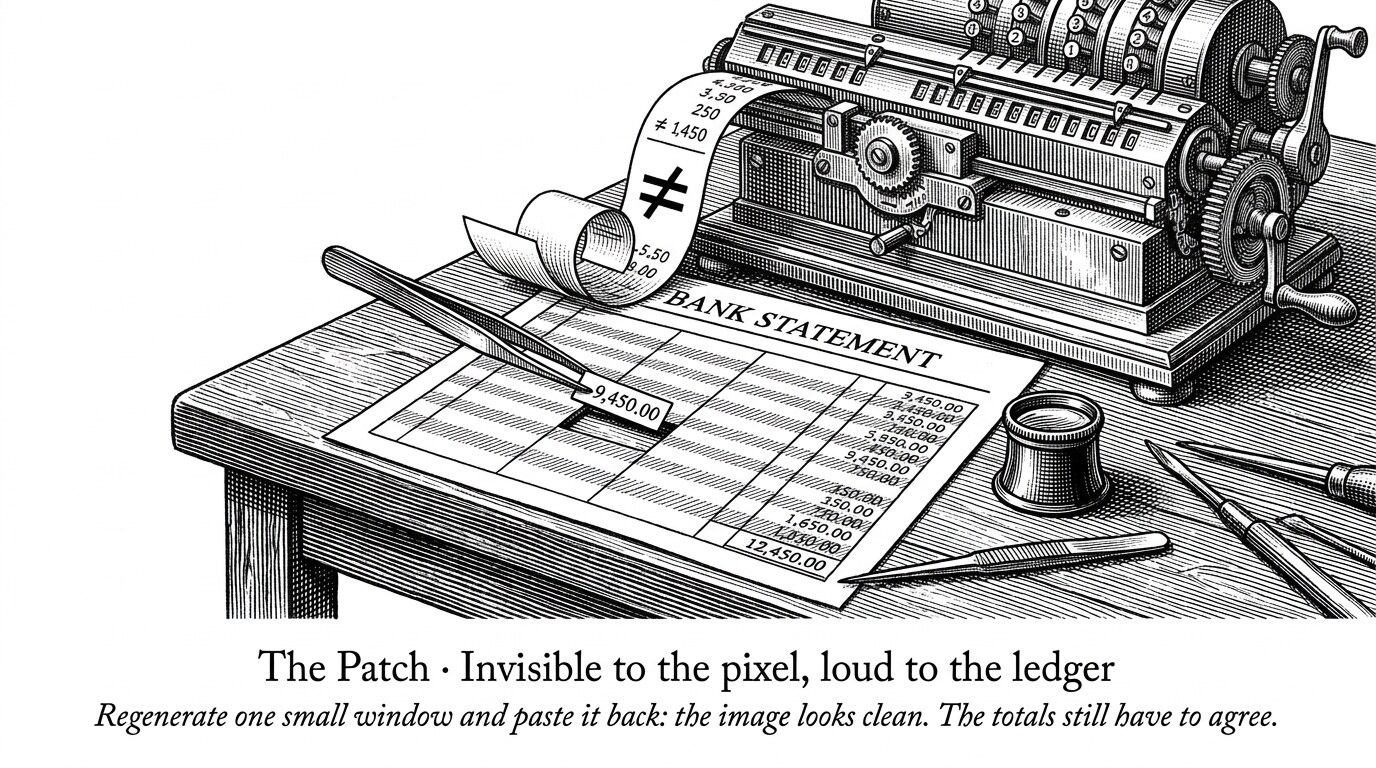
Here is the catch, and why pixel detection can't stand alone: when a forger cuts out a small patch, regenerates only that, and pastes it back, detection drops to nearly zero. Between 0% and 4%, even at native resolution.
Two layers, two blind spots, no overlap
Share of AI-regenerated pages caught, at a threshold that flags 1% of genuine pages.
That's where the layers stop being a checklist and start covering for each other. An image model asked to change one number on a dense page tends to redraw all of it: digits elsewhere shift, words come back slightly garbled. The pixel detector sees the re-render. And a careful forger who regenerates only a small patch to slip past it walks straight into the balance equation, the IBAN checksum and the cryptographic seal.
Two smaller habits matter here too. We read every image upload before converting it to PDF, because conversion erases the JPEG history, the camera's embedded thumbnail and any provenance claim. Some generators label their own output as AI-made in the file's metadata, and nobody forges that label against themselves. Stripped copies won't carry it, so its absence means nothing. Its presence means a lot.
Not checked is not passed
The single most important rule in our fraud engine is boring: when a check can't run, it says so.
Most scans have no parser that reads them, so the arithmetic can't run. Many documents match no reference template, so the template comparisons can't run. A green dot next to a check means "checked, nothing found". Showing that dot for a check that never ran tells the reviewer a scan was verified when it wasn't even read.
A hollow dot is not a green one
How an analysis reports a scan from a bank our parsers don't read yet.
We learned this the hard way. In production, the exact same file once scored 98.75 (high risk), and three hours later 0.0 (trusted). On the first run, the visual template match came back empty. Instead of abstaining, six checks fell back to a generic bank-statement baseline and flagged an ordinary document as wildly abnormal. Now those checks abstain, the analysis says "not checked" with the reason, and a missing comparison can cost a document its trusted badge but can never condemn an applicant.
Two numbers, not one
A fraud detector has two ways to fail. It can flag honest people, and it can miss forgeries. Most published accuracy figures measure one of them, on a set nobody else can see.
We keep both, and measure both against every change.
Precision, on what customers actually upload. Before any signal change ships, we replay it against stored production analyses. When we tightened our verdict rules to require contradictions instead of piled-up anomalies, the high-risk pile on 224 customer documents from a 30-day window went from 90 to 9, and none of the forgeries we had confirmed by hand left it.
Recall, on forgeries we make ourselves. Nobody hands you a labelled set of the fraud you missed, so we build our own: genuine documents, forged dozens of ways, every fake run through the real pipeline. On 2,080 forgeries, adding the content checks above took the catch rate from 35.4% to 63.6%. Before them, forgeries whose only flaw was that the figures disagreed were caught 5% of the time.
Both directions, measured before every change
63.6% means about a third still gets through. We publish that number because the alternative is publishing a better-looking one we couldn't defend. The benchmark also tells us exactly which third: an edited account holder name (0 of 48), statements no parser reads, a careful edit that repairs every total. That list is the roadmap.
Where this leaves us
At Holofin, document fraud is one of the problems we're paid to be paranoid about, and the work above follows a few rules we didn't start with:
- A verdict rests on a contradiction. Counts and anomalies rank the queue. Only a document that cannot be true gets condemned.
- Every comparison needs a reference, or it abstains. The issuer's matched template, or what this PDF producer normally emits. Otherwise, "not checked".
- Read the claim, not just the container. Figures to the cent, dates the bank actually printed, checksums, seals against the issuer's key, the issuer's look.
- Never trust the text layer for a figure. What a page draws and what it says can differ, on purpose.
- Measure both directions. Precision on real traffic, recall on forgeries, before every change.
In practice, that's 92 signals across file structure, typography, metadata, pixels, cryptographic seals and financial arithmetic, each able to point at the page, the region and, when it can, the field that failed.
A forger can wash away how a document was made, and make what's left look real. What it says still has to be true: to the cent, against the issuer's key, in the issuer's own look. That part doesn't come out in the wash.
Related Articles
Forest and the case for treating the decision as infrastructure, not an inbox
Forest made the case that OCR deserves to be treated as infrastructure rather than a commodity. This is the companion argument from upstream: the layer that receives the data deserves the same seriousness, because a perfectly extracted figure can still wait three days, get approved by the wrong person, and leave no record that it happened.
Your Table Extractor Passed. The Numbers Didn't.
An auditor opens your extraction output for a balance sheet. The model reports 99.2% cell accuracy. Impressive. Then she totals the asset column by hand, the way auditors do, and it comes to a number that is off by one row. Assets no longer equal liabilities plus equity. The statement does not close.
Document Fraud Detection: What a PDF Can't Hide
We used to think document fraud was a visual problem. Wrong fonts. Misaligned columns. A logo that felt slightly off. We built checks around what humans see, because what humans see is all we had.